
Short answer: Nemotron 3.5 Bolt 74B-A9B is an open-weight, mixture-of-experts model from NVIDIA built for local agent work such as tool calls, web browsing and terminal tasks. It has 74B total parameters with about 9B active per token, and NVIDIA quantized its expert weights to roughly 2 bits so the weights fit in 24 GB. Weights are on Hugging Face under the OpenMDW-1.1 license, which the model card says allows commercial and non-commercial use. An independent index puts it 4th of 67 in its class, but most other numbers are NVIDIA’s own, and its speed in NVIDIA’s own table trails two rivals.
What is Nemotron 3.5 Bolt?
According to the model card as summarized by OrcaRouter, Bolt is a hybrid of Mamba-2 and Transformer layers with a mixture-of-experts backbone and a vision encoder, so it accepts text, images and video and outputs text. Context goes up to 256K tokens. NVIDIA says it was derived from the larger Nemotron 3.5 Super VL (120B total, 12B active) through architecture search and quantization-aware distillation. Baseten’s listing matches the size, input types and license.
NVIDIA announced it on Oct 15, according to OrcaRouter, and TechCrunch covered the launch on Oct 19. A smaller Bolt E4B (4 GB) is listed for Oct 23.
Will it really fit in 24 GB?
Only the weights are meant to. The 24 GB figure covers weights, not images, video frames, conversation history or tool results, which all use extra memory. OrcaRouter also notes that Ollama lists a 25 GB tag, which is already above 24 GB before any context. So a 24 GB card is a tight fit at best. Check the file size of the exact version you plan to download.
| Item | What the sources say |
|---|---|
| Total / active parameters | 74B / about 9B per token |
| Expert weights | about 2 bits (IQ2_XXS) |
| Context window | up to 256K tokens |
| License | OpenMDW-1.1 |
| Runtimes | vLLM (NVIDIA Ampere, Hopper, Blackwell), llama.cpp, Ollama (CUDA only) |
| Apple Silicon in Ollama | not supported yet, per the model card summary |
How good is it, and who measured it?
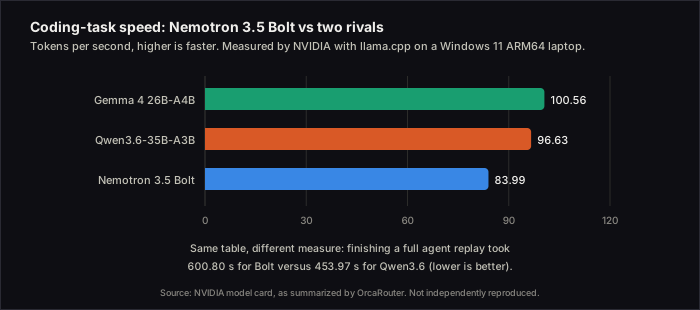 Speed figures are NVIDIA’s, measured with llama.cpp on a Windows 11 ARM64 laptop.
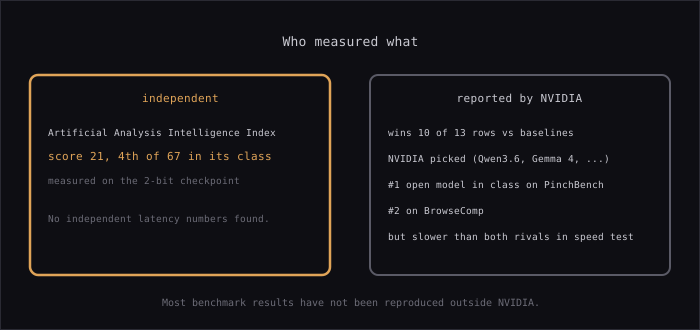 Most results have not been reproduced outside NVIDIA.
The only independent number found is an Artificial Analysis Intelligence Index score of 21, 4th of 67 models in its comparison class, measured on the 2-bit checkpoint. NVIDIA’s own 13-benchmark table has Bolt ahead on 10 rows against Qwen3.6-35B-A3B, Gemma 4 26B-A4B and Nemotron 3.5 Lightning 30B-A3B, but NVIDIA chose those baselines. NVIDIA also reports it as the top open model in its class on PinchBench and second on BrowseComp. In the same table, Bolt is slower than both Qwen3.6 and Gemma 4 at generating coding tokens, and an end-to-end agent replay took longer than Qwen3.6 (600.80 s versus 453.97 s).
Who should care?
For other models by memory size, see our open-weight coding models by hardware guide. Bolt’s bigger sibling is covered in the Nemotron 3.5 Super VL post.
- If you run local agents on an RTX or DGX-class machine: worth trying, since the license is permissive and the model is built for tool use and browsing.
- If you are on Apple Silicon: wait for Ollama support or look for community MLX conversions, which the model card summary says have appeared.
- If you care about raw speed: NVIDIA’s own table says look at Qwen3.6 or Gemma 4 first.
What I am unsure about
- How it performs on your tasks. I have not run it, and there are no independent latency numbers yet.
- How much quality the 2-bit quantization costs. The independent score was measured on the 2-bit version, which is a good sign, but one index is not a full picture.
- The exact launch date. OrcaRouter dates the announcement Oct 15 and says the Hugging Face repository was created Oct 7, while TechCrunch, dated Oct 19, says “Thursday.” Oct 15 was a Thursday, so I use that.
FAQ
Is it open source?
It is open-weight under OpenMDW-1.1. That means you can download and run the weights, which is not always the same as open source.
What does “A9B” mean?
About 9 billion parameters are active for each token, even though the full model has 74B.
Can it run on my laptop?
Only if you have enough memory for the weights plus context, roughly 24 GB or more, and a supported runtime.
Sources
- Nemotron 3.5 Bolt quiet release — OrcaRouter
- Nvidia launches new open models to run agents in the enterprise and on PCs — TechCrunch
- NVIDIA Nemotron 3.5 Bolt 74B-A9B 24GB — Baseten
Written with AI assistance and checked against the sources above. See About for how ossbeat works.


